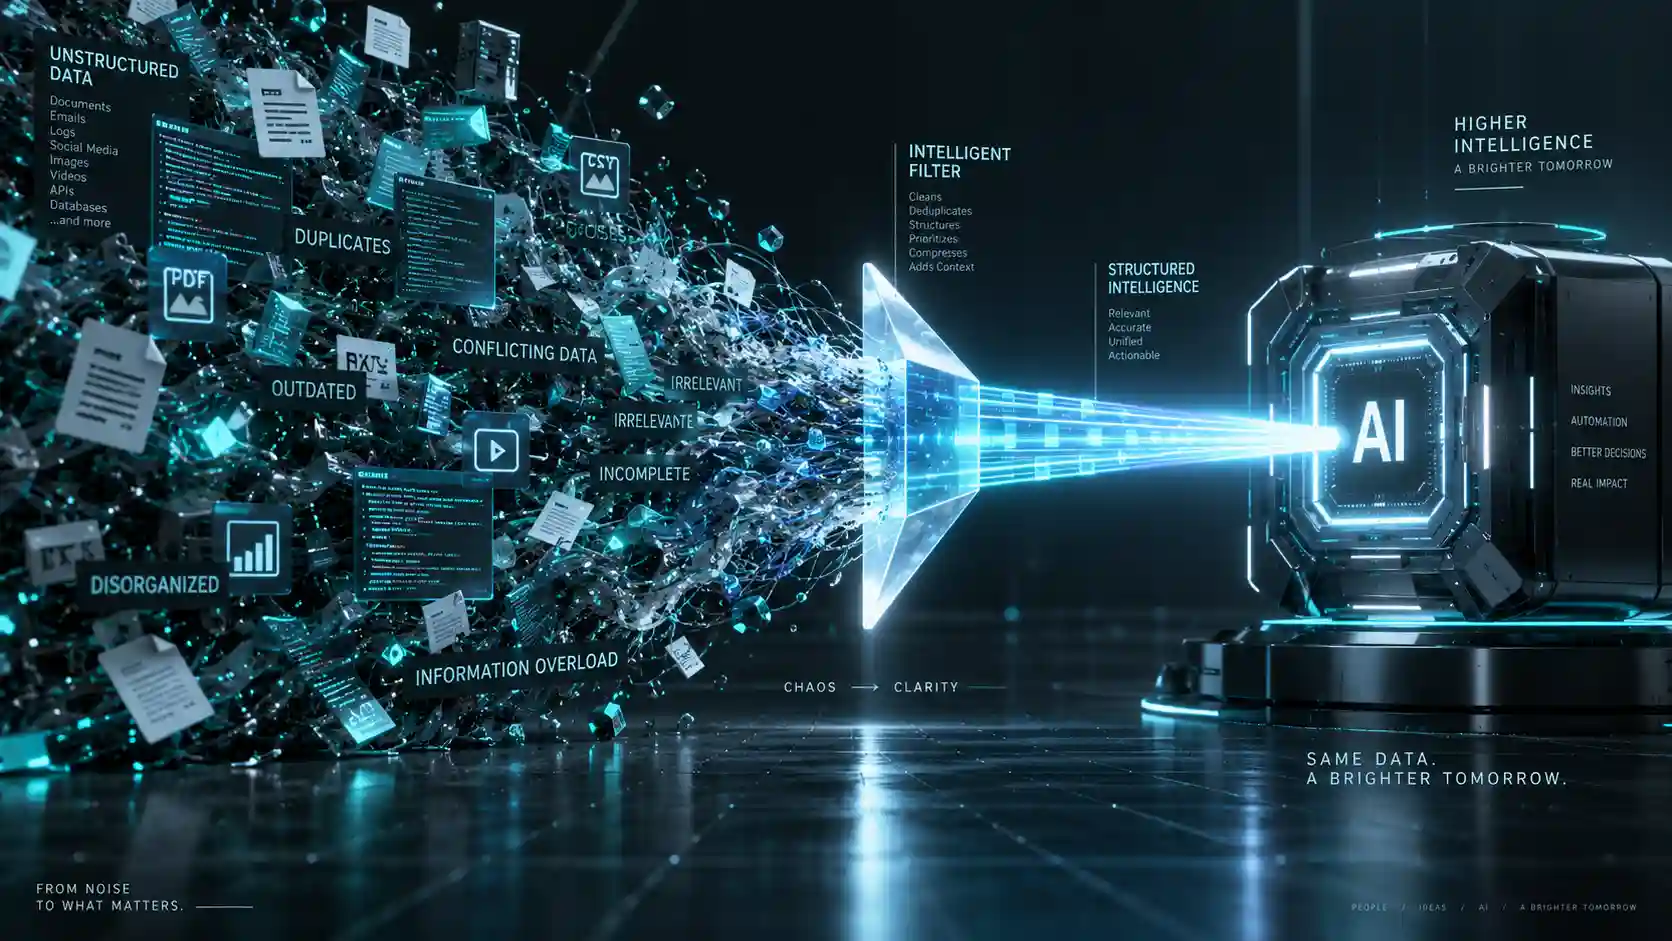
When million-token context windows first debuted, the enterprise consensus seemed obvious: why bother with complex retrieval pipelines when you can just feed your entire codebase, database schema, or 500-page policy binder directly into the prompt?
Two years later, engineering teams are learning a costly lesson.
Dumping massive payloads into LLM context windows hasn't made AI agents smarter—it has made them slower, significantly more expensive, and surprisingly less accurate.
At Cynked, we routinely audit enterprise agent deployments where 80% of the API spend is consumed by redundant context overhead. This issue—Context Window Bloat—is currently one of the single largest drivers of negative ROI in enterprise AI projects.
Here is why context bloat happens, what it actually costs your business, and how leading engineering teams build lean context architectures that scale efficiently.
The Hidden Costs of Context Window Bloat
Context bloat manifests in three distinct ways across your infrastructure and financial statements:
1. Exponential Cost Scaling
LLM pricing is directly tied to input and output tokens. A workflow that passes 250,000 tokens of raw documentation per invocation might only cost a fraction of a cent on lighter models, but at enterprise scale—processing 50,000 customer inquiries or financial reconciliations per month—that context overhead translates into tens of thousands of dollars in unnecessary API costs.
2. Latency Spikes Destroying User Experience
Time-to-first-token (TTFT) increases drastically as input context grows. When an agent has to ingest 100k+ tokens before generating its first reasoning step, response latency jumps from milliseconds to 6–12 seconds. For customer-facing bots or real-time operational assistants, that delay destroys adoption.
3. "Lost in the Middle" Accuracy Degradation
Research across major frontier models consistently proves that LLMs suffer from attention degradation when processing ultra-long contexts. Information located in the middle of a massive context payload is frequently overlooked compared to data placed at the very beginning or end.
Passing more data often results in worse answers.
The 4 Principles of Lean Context Architecture
High-performing enterprise agents don't rely on brute-force context windows. Instead, they use a Lean Context Architecture to deliver precise, minimal context to the model at each step of execution.
┌────────────────────────────────────────────────────────┐
│                 Incoming Task / Prompt                 │
└───────────────────────────┬────────────────────────────┘
                            │
                            ▼
┌────────────────────────────────────────────────────────┐
│            1. Intent & Scope Classification            │
└───────────────────────────┬────────────────────────────┘
                            │
                            ▼
┌────────────────────────────────────────────────────────┐
│        2. Dynamic Agentic Retrieval (RAG/Tools)        │
│      (Fetches only top-k relevant chunks & metadata)   │
└───────────────────────────┬────────────────────────────┘
                            │
                            ▼
┌────────────────────────────────────────────────────────┐
│           3. Context Budgeting & Compaction            │
│       (Strips raw JSON, summarizes prior history)      │
└───────────────────────────┬────────────────────────────┘
                            │
                            ▼
┌────────────────────────────────────────────────────────┐
│              4. Targeted LLM Execution                 │
│           (Lean context = Fast + Accurate)             │
└────────────────────────────────────────────────────────┘
1. Implement Strict Context Budgeting
Treat your prompt context like a memory budget in software engineering. Define a maximum token limit for system instructions, retrieved knowledge, and conversation history (e.g., 4,000 tokens for routine tasks). If a retrieval step exceeds the budget, enforce automated summarization or dynamic pruning before calling the main model.
2. Shift from Passive Context to Active Agentic Retrieval
Instead of loading all potentially relevant documents upfront, equip your agent with targeted tools to query database indices, vector stores, or search APIs on demand. The agent should ask for specific data only when it realizes it needs it.
3. Prune Raw Payloads into Structured Schema Snippets
Sending raw REST API responses or full JSON blobs into a prompt wastes thousands of tokens on structural syntax (brackets, null values, repeated keys). Transform API outputs into lean, minified markdown tables or key-value pairs before feeding them to the model.
4. Separate Reasoning Layers from Execution Layers
Use smaller, faster models to perform intent classification, routing, and context filtering. Only invoke high-capability reasoning models once the context has been sanitized and compressed down to its essential elements.
Realistic Results: What Optimization Looks Like
When enterprise teams transition from brute-force context to a Lean Context Architecture, the impact on performance metrics is immediate:
- 📉 60%–80% reduction in monthly LLM token costs.
- ⚡ 3x–5x faster response times (sub-second TTFT for common agent steps).
- 🎯 15%–25% improvement in task completion accuracy due to reduced context noise.
Bottom Line
Large context windows are an extraordinary capability for exploratory analysis and one-off document queries. But for production AI agents running thousands of times per day, relying on huge prompts is a design flaw.
Building scalable, cost-effective AI agents isn't about how much data your model can swallow—it's about how effectively your architecture filters out the noise.
Need help optimizing your enterprise AI stack for performance and cost?
Book a discovery call with Cynked to audit your current agent architectures, eliminate token bloat, and build production systems that deliver measurable ROI.
Need a scalable stack for your business?
Cynked designs cloud-first, modular architectures that grow with you.
Related Articles
Embedded AI vs Bolt-On Tools: The 6x Failure Gap
AI tools bolted onto existing workflows fail 6x more often than embedded ones. Here's how to embed AI inside your business processes for real ROI.
Vertical AI Agents Deliver 500% ROI: A Buyer's Guide for 2026
Vertical AI agents return ~500% ROI vs ~171% for horizontal tools. Learn when to pick specialized agents, how to evaluate vendors, and avoid costly mistakes.
Only 12% of AI Agents Reach Production: What Winners Do
78% of enterprise AI agent pilots never scale. Here's the structural playbook the 12% who succeed are using to ship agents to production in 2026.